I work on video foundation models, from large-scale pretraining to post-training and real-time generation. At Pika, I lead research across model training, alignment, and distillation.
Previously at MiniMax, working on Hailuo video and image models. Ph.D. from Shanghai Jiao Tong University.
Leading video-model post-training, real-time audio-video generation, and agentic video systems. Research spans SFT, RLHF, distillation, data, and production deployment.
My earlier research explored local features, neural scene representations, and real-time robotic perception. These publications appear under the name Shenghao Li. * Corresponding author.
An online scene representation method that handles unknown camera poses, boundary ambiguity, and observation noise such as camera motion blur, producing sharp and compact representations of scenes under a wide range of shooting conditions.
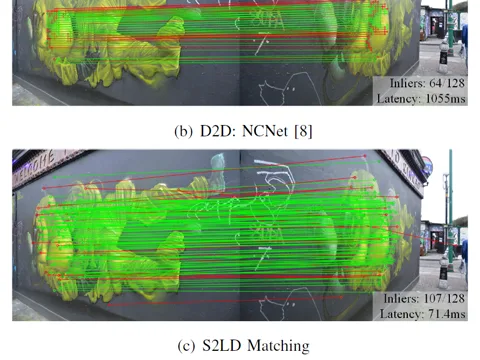
A fully differentiable correspondence estimation method guided by epipolar geometry. S2LD asymmetrically establishes correspondences with consistent sub-pixel coordinates while reducing the cost of matching; salient features are explicitly located, descriptions are conditioned on both views via attention, and correspondences are refined progressively across multiple levels to reduce re-projection error.
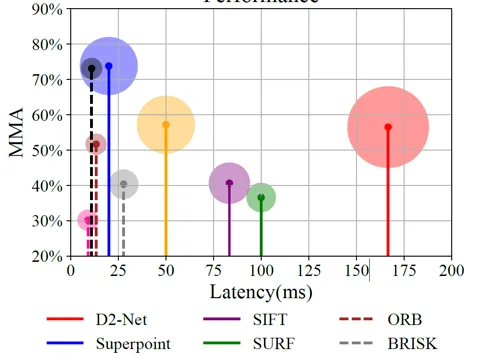
A quantized self-supervised local feature for indirect VSLAM that stays robust to environmental interference in robot localization, while running in real time.
A single-input multi-output model for feature extraction, together with a descriptor quantization approach that embeds features into Hamming space for efficient matching on mobile platforms.
Advisor: Prof. Qunfei Zhao Weichai Power Scholarship · Top 1%
2013 — 2020
East China University of Science and Technology
M.S., Mechanical Engineering B.Eng., Mechanical Engineering & English
Earlier projects 3D avatars, industrial vision & robotics
Animatable Avatar
MiniMax, 2022–2023
During my internship at MiniMax I helped build a pipeline for creating NeRF-based animatable avatars, driven by facial keypoints, audio, SMPL, and other signals, along with a LightStage data pipeline used to capture 500+ subjects.
Vision-based Multi-truss Workpiece Grabbing
Industrial deployment, 2021–2022
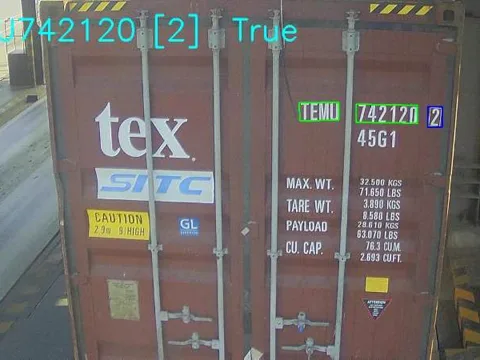
A 3D pose estimation method for densely stacked complex workpieces with an RGB-D camera, and a vision-based grabbing algorithm with a line-scan camera and a multi-truss system, deployed in production.
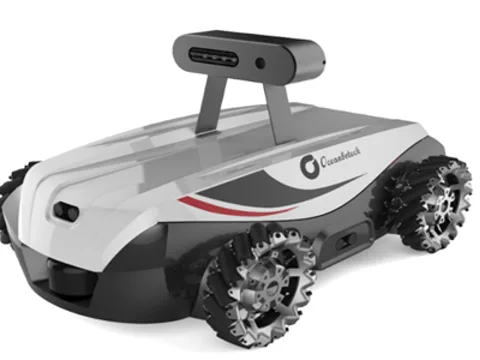
An open-source intelligent mobile platform with mecanum wheels, equipped with an RGB-D camera, 2D LiDAR, IMU, and odometry. The package provides Gazebo simulation, 2D SLAM, visual SLAM, object tracking, navigation, and autonomous driving.
 Real-time video generation